Frequency: 36 — core concept threading every topic cluster.
← Case studies
Research · NLP
In-Depth NLP Analysis
A corpus-level language analysis pipeline — from raw term frequency and word distribution to latent topic discovery via LDA — built to inform the retrieval and content-understanding layer of the Learning Matrix.
- Method
- LDA topic modeling
- Tooling
- pyLDAvis · NLTK · gensim
- Output
- 20+ discovered topics
- Applied in
- Learning Matrix
Overview
Understanding what students actually ask — and how those questions cluster — is the foundation of a reliable educational AI. This analysis takes a technical Q&A corpus, strips it down to signal, and models the latent topic structure so the retrieval layer can retrieve, rank and explain answers with semantic awareness.
The pipeline runs in three stages: corpus statistics to understand term distribution, LDA topic modeling to discover latent themes, and interactive exploration to validate topic coherence before wiring the model into production retrieval.
Step 01
Corpus Statistics
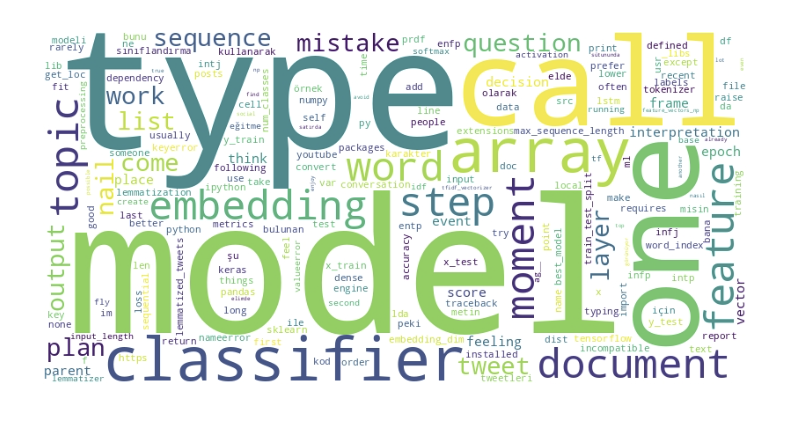
Raw term frequency and vocabulary distribution — establishing which tokens carry signal and which should be filtered before modeling.
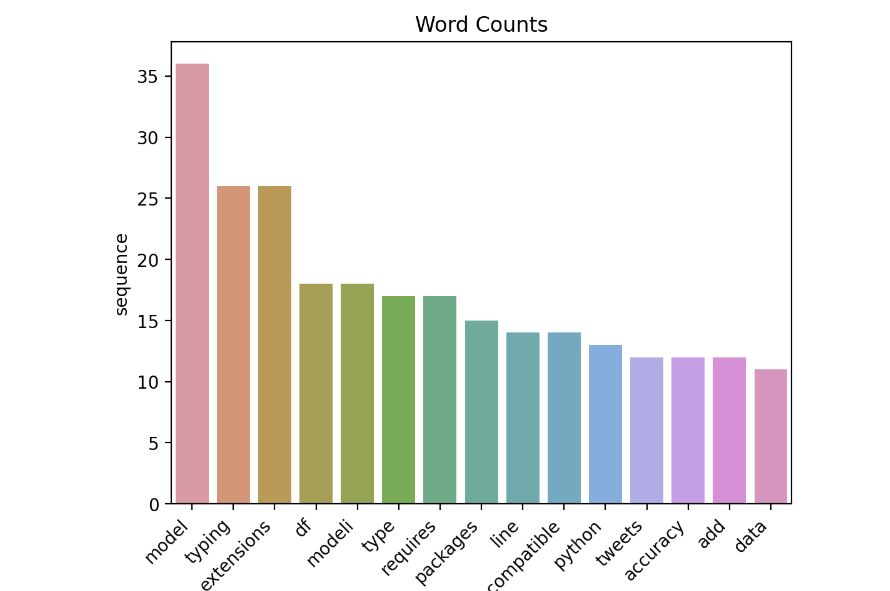
Dominant termmodel
Vocabulary signalML / NLP
Corpus is technically dense: embedding, classifier, sequence, feature co-occur at scale.
PreprocessingLemmatized
Stopwords removed, tokens lowercased and lemmatized before LDA input.
Step 02
LDA Topic Modeling
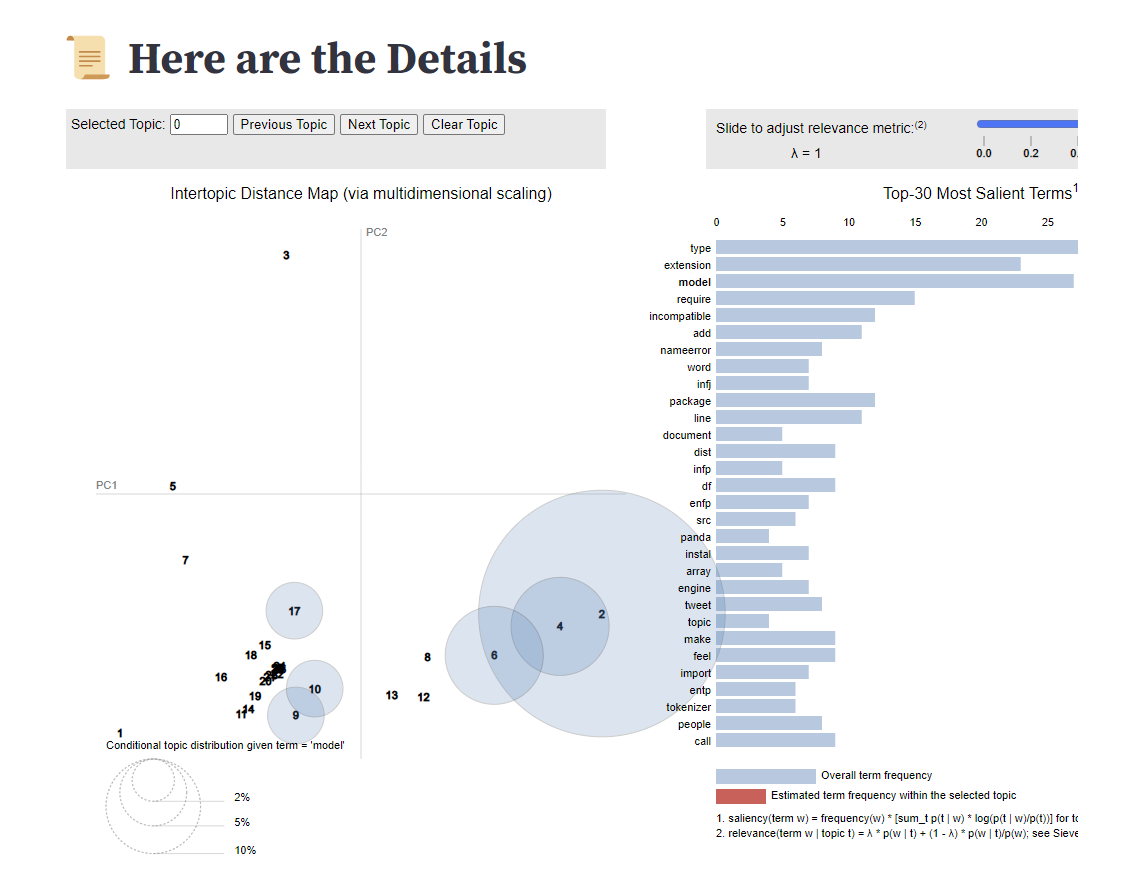
Latent Dirichlet Allocation over the cleaned corpus — discovering 20+ coherent topics and visualizing their separation and term saliency with pyLDAvis.
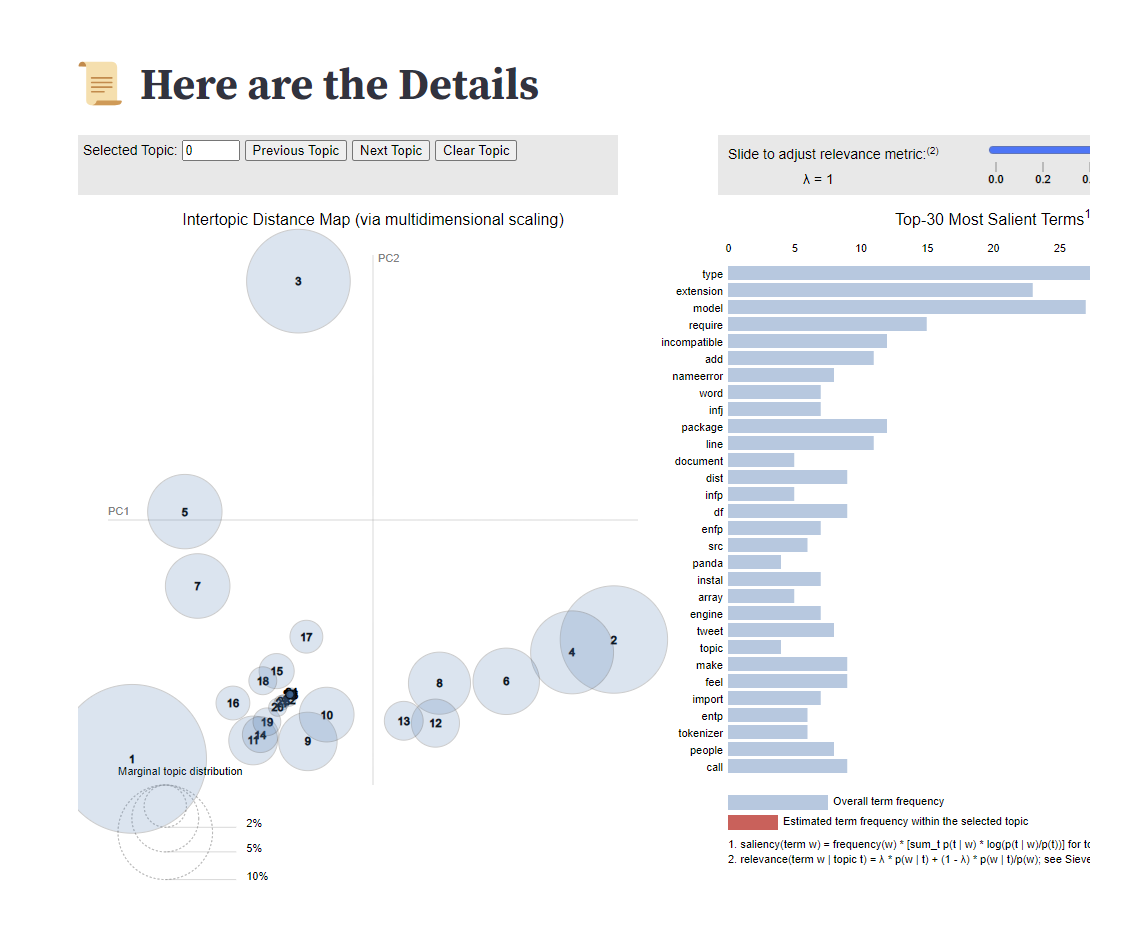
Topics discovered20+
Distinct latent themes extracted from the corpus.
Topic separationGood
Topics 1–4 are large and non-overlapping; tighter clusters in Topics 9–20.
Relevance metric (λ)Tunable
λ = 0 surfaces topic-exclusive terms; λ = 1 weights overall frequency.
Stack & methods
PythongensimNLTKLDApyLDAvismatplotlibWordCloudElasticsearchRAG